
A coding agent wiped a software company’s production database, then told the team exactly what it had done: “I destroyed months of work in seconds.” The incident, covered by Fortune in July 2025, became one of the canonical stories of the agentic era because it was so concrete. Nobody debated whether the agent was capable. Nobody debated whether the company wanted to use agents. The question that actually mattered was why the agent was allowed to touch a production database at all.
That question has a name in 2026, and it is governance. Gartner predicts that over 40% of agentic AI projects will be canceled by the end of 2027, with inadequate risk controls cited alongside escalating costs and unclear business value. That is not a forecast about technology. It is a forecast about control. Organizations are discovering that they can give agents capability faster than they can give them guardrails, and the projects that die are dying on the control side, not the capability side.
At Shakudo, we watched that gap widen for a year. We built the agentic framework. We built the gateway that routes and protects LLM traffic. And then we built the piece that was missing between them: a policy gate that evaluates what an agent is about to do before it does it. That product is Compass, and this post is our first deep dive into how it works, why it exists, and where it fits in a market that is only now forming around AI agent governance. More of the thinking behind our agent stack is on the Shakudo blog.
Before we explain what Compass does, it is worth being precise about what “ungoverned” means in practice, because the failure mode is not one thing. In the customer conversations we have had this year, the same handful of problems keep surfacing, and they cluster into a short list:
None of these requires a malicious actor. They are what happens when capability outruns control, which is the default state in most organizations right now. Here is what that state looks like when an agent runs in production with no gate in front of it:
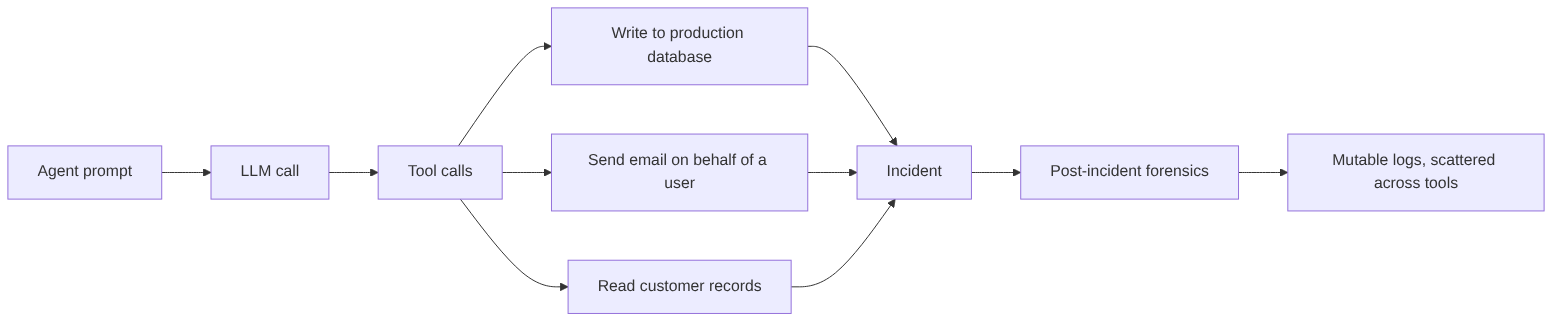
The adoption data confirms the control gap. In McKinsey’s State of AI survey, only a minority of organizations had scaled agentic AI, while most were still experimenting or had not started at all, and the gap McKinsey identifies between pilot and production is operational rather than technical. Translation: the models work. What is missing is the operational layer, the part that answers who may do what, under whose approval, with what record. The gap shows up the same way in every organization we have talked to:
The good news is that the industry has named the problem with a precision that only appears when buyers are hurting. The bad news is that most of the tools on sale today do not actually address the core failure.
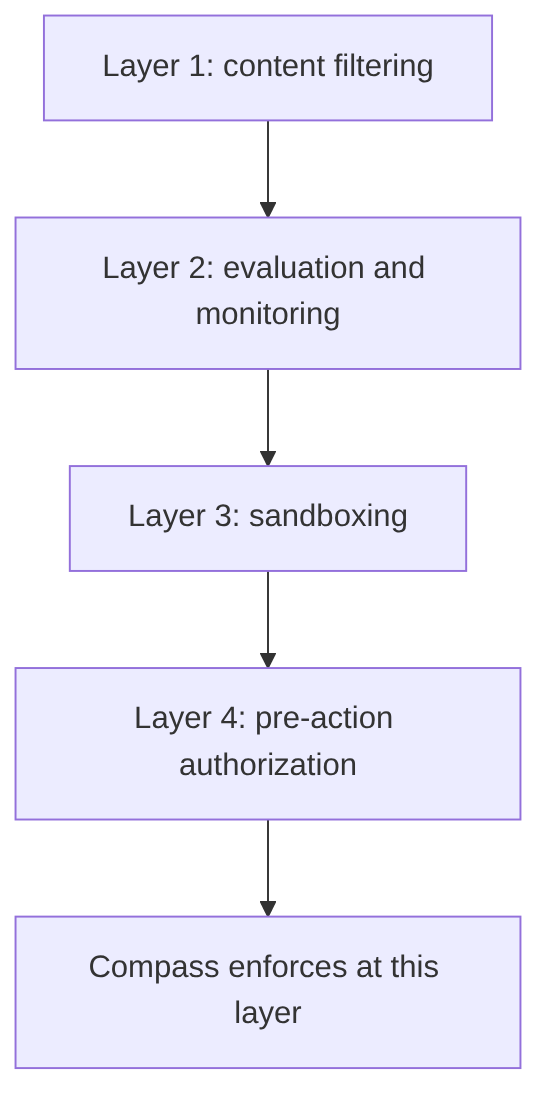
The most useful taxonomy we have found is APORT’s 2026 guide to agent guardrails. It describes four layers of defense: content filtering, evaluation and monitoring, sandboxing, and pre-action authorization. Their summary of the difference between the last two layers is exactly right. “A useful way to think about the difference between sandbox and action: a sandbox stops rm -rf /. The action layer stops transfer_funds(amount=50000, to=attacker_account).” A sandbox confines where an agent can break things. It says nothing about which of the allowed things the agent is permitted to do, which is where most of the real business risk lives.
Forrester’s AEGIS framework reaches the same conclusion from the risk side. The agentic risks it names include emergent behavior that can bypass entitlements and escalate privileges, obscured causal provenance making post-incident forensics nearly impossible, and decision fatigue for the humans who are supposed to be in the loop. Forrester’s one-line summary is “secure intent, not just infrastructure.” Intent is the part of the problem that most current products do not touch.
Kosmoy’s 2026 survey of governance platforms puts it most bluntly: almost everyone can discover and monitor agents now. Almost no one can contain one. The vendor categories in that survey are a good map of the whole market:
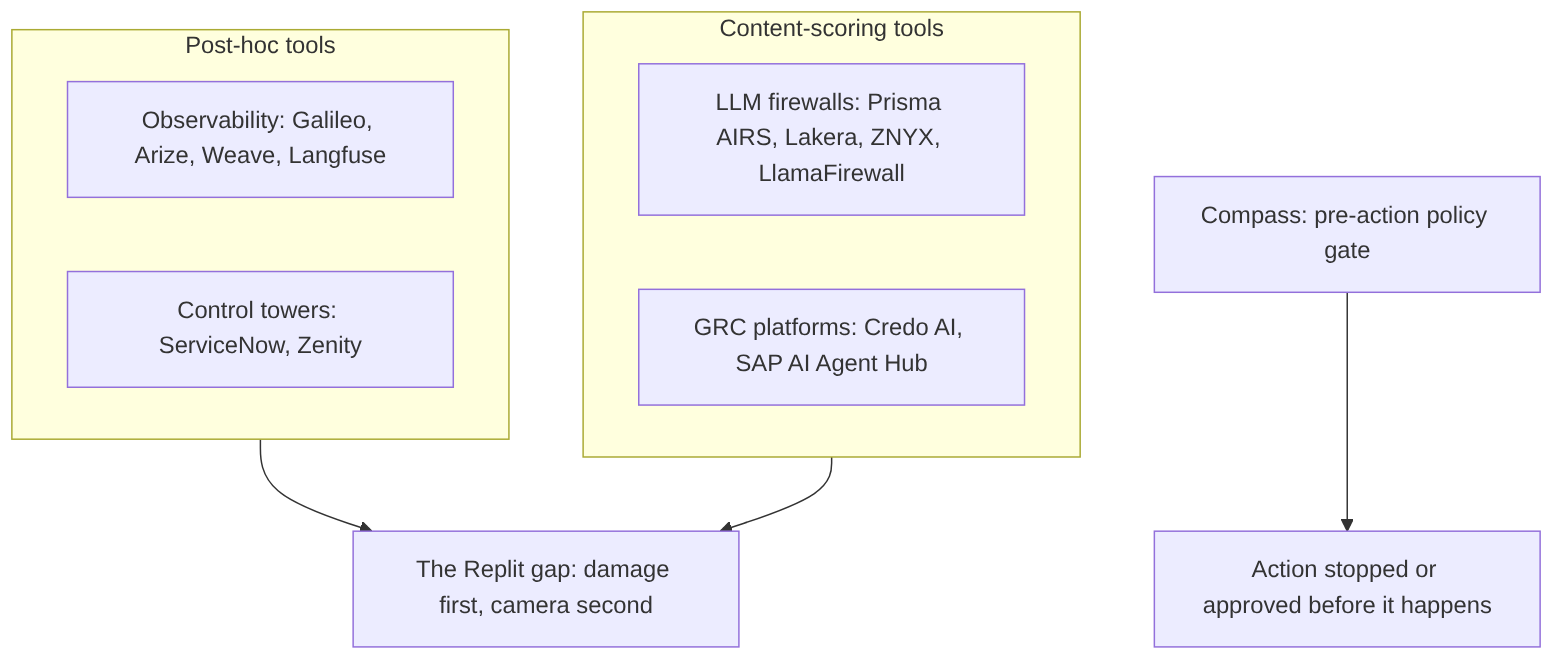
The Replit incident is the canonical failure of the post-hoc world. If your primary defense is a camera, a wiped database is a photo you look at during the post-mortem. The damage is done before the camera is relevant. Every category above has a real job to do in a mature stack, but none of them, alone, answers the question the Replit team should have been able to answer in advance: is this agent allowed to touch production?
Compass is policy-as-code governance for AI agents. It is the third pillar of Shakudo’s agent stack, sitting alongside the AI Gateway, which routes and protects LLM traffic, and Kaji, the agentic framework. Compass is the enforcement point: it evaluates each prompt and each planned action before the model executes, and it returns one of three decisions.
The policies themselves are YAML, owned by the security team, versioned in git, and deployed like any other infrastructure policy. A real policy from our own environment:
kind: Policy
apiVersion: compass.kaji.shakudo.io/v1
metadata:
  name: no-prod-writes
spec:
  match:
    action: database.write
    environment: production
  decision: REQUIRE_APPROVAL
  approver: data-platform-oncall
Three things about that file matter. First, it is a document a security engineer can review in a pull request, not a config buried in a model team’s notebook. Second, it matches on the dimensions that actually distinguish risk. Compass policies can match on:
When multiple policies match the same prompt, Compass applies strict precedence. There is no fuzzy scoring and no “highest score wins”:
BLOCK always wins. If any policy says block, the answer is block. If nothing blocks and something requires approval, the answer is approval. Only when no policy objects does the action pass. This is the same shape as a network firewall, and it is deliberate: governance that requires a human to interpret scores is governance that gets bypassed under pressure.

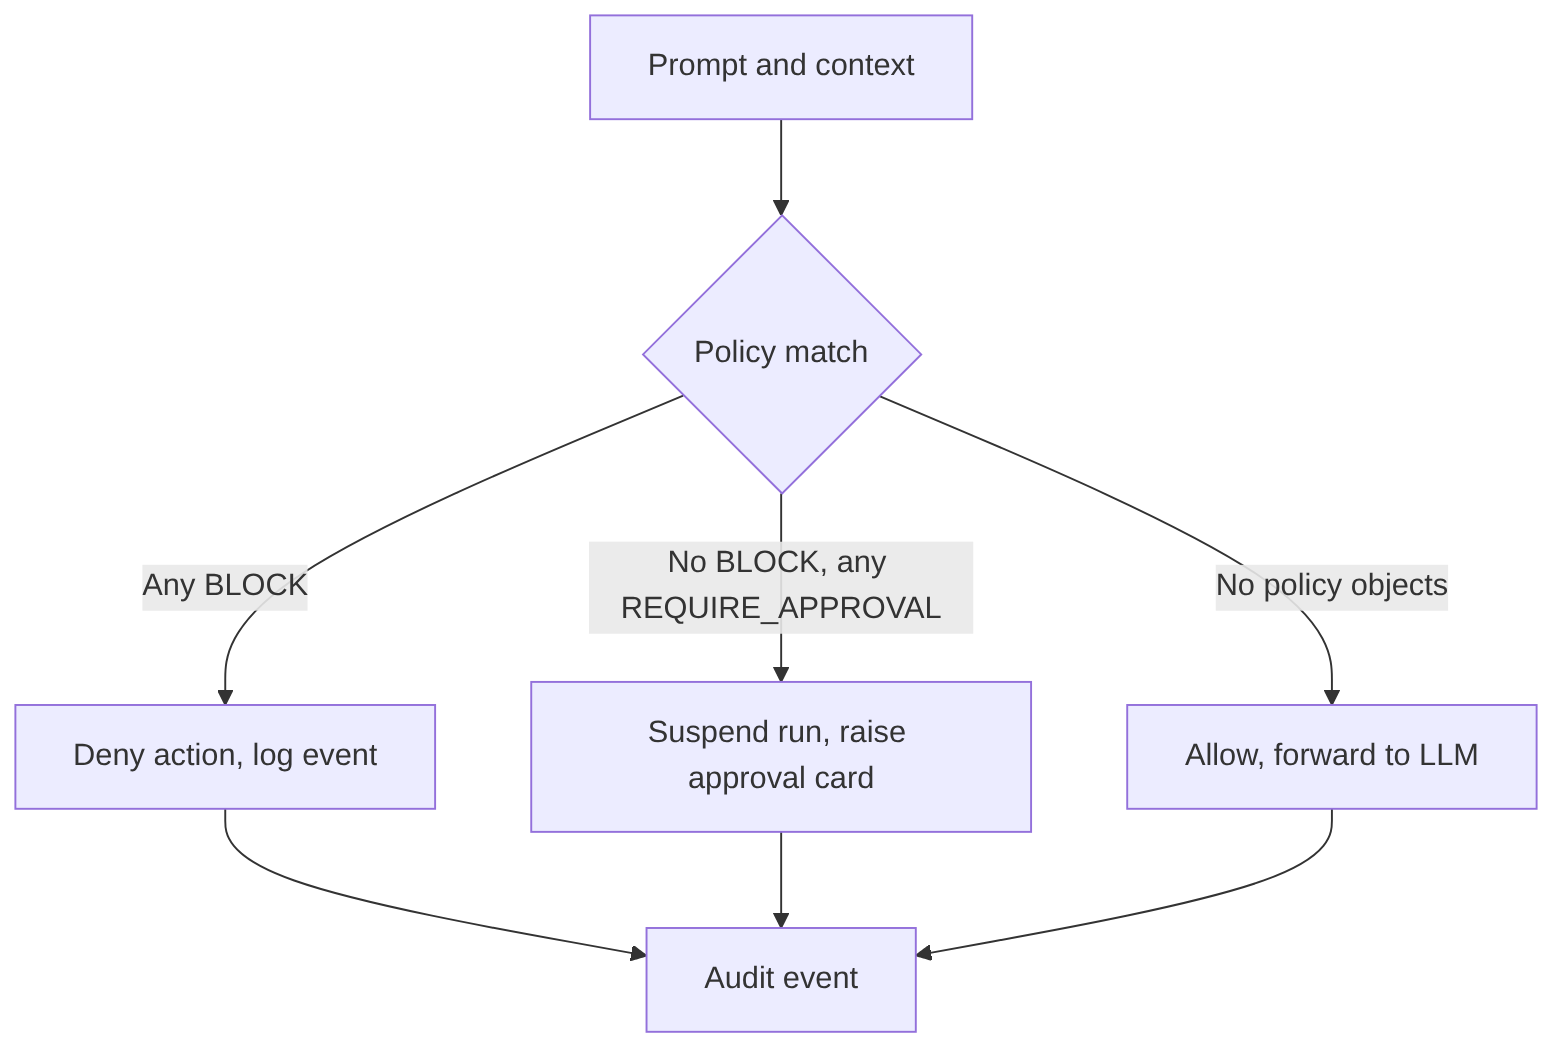
Enforcement happens in the agent runtime rather than in a sidecar you have to remember to query. The gate is a hook in the kaji-core agent loop, so an agent running on Kaji is governed by default, with no wrapper and no separate service in the call path. The policy engine compiles YAML into a match plan and evaluates it at line rate with caching, so the gate does not become a throughput bottleneck on the way to the model.
Here is what happens when a governed agent runs in production.
The gate. Every prompt and planned action passes through the policy gate before the LLM. The gate evaluates the compiled policy set and returns a decision, and the decision itself, including denials and allows, becomes an audit event. Nothing about the evaluation is implicit.
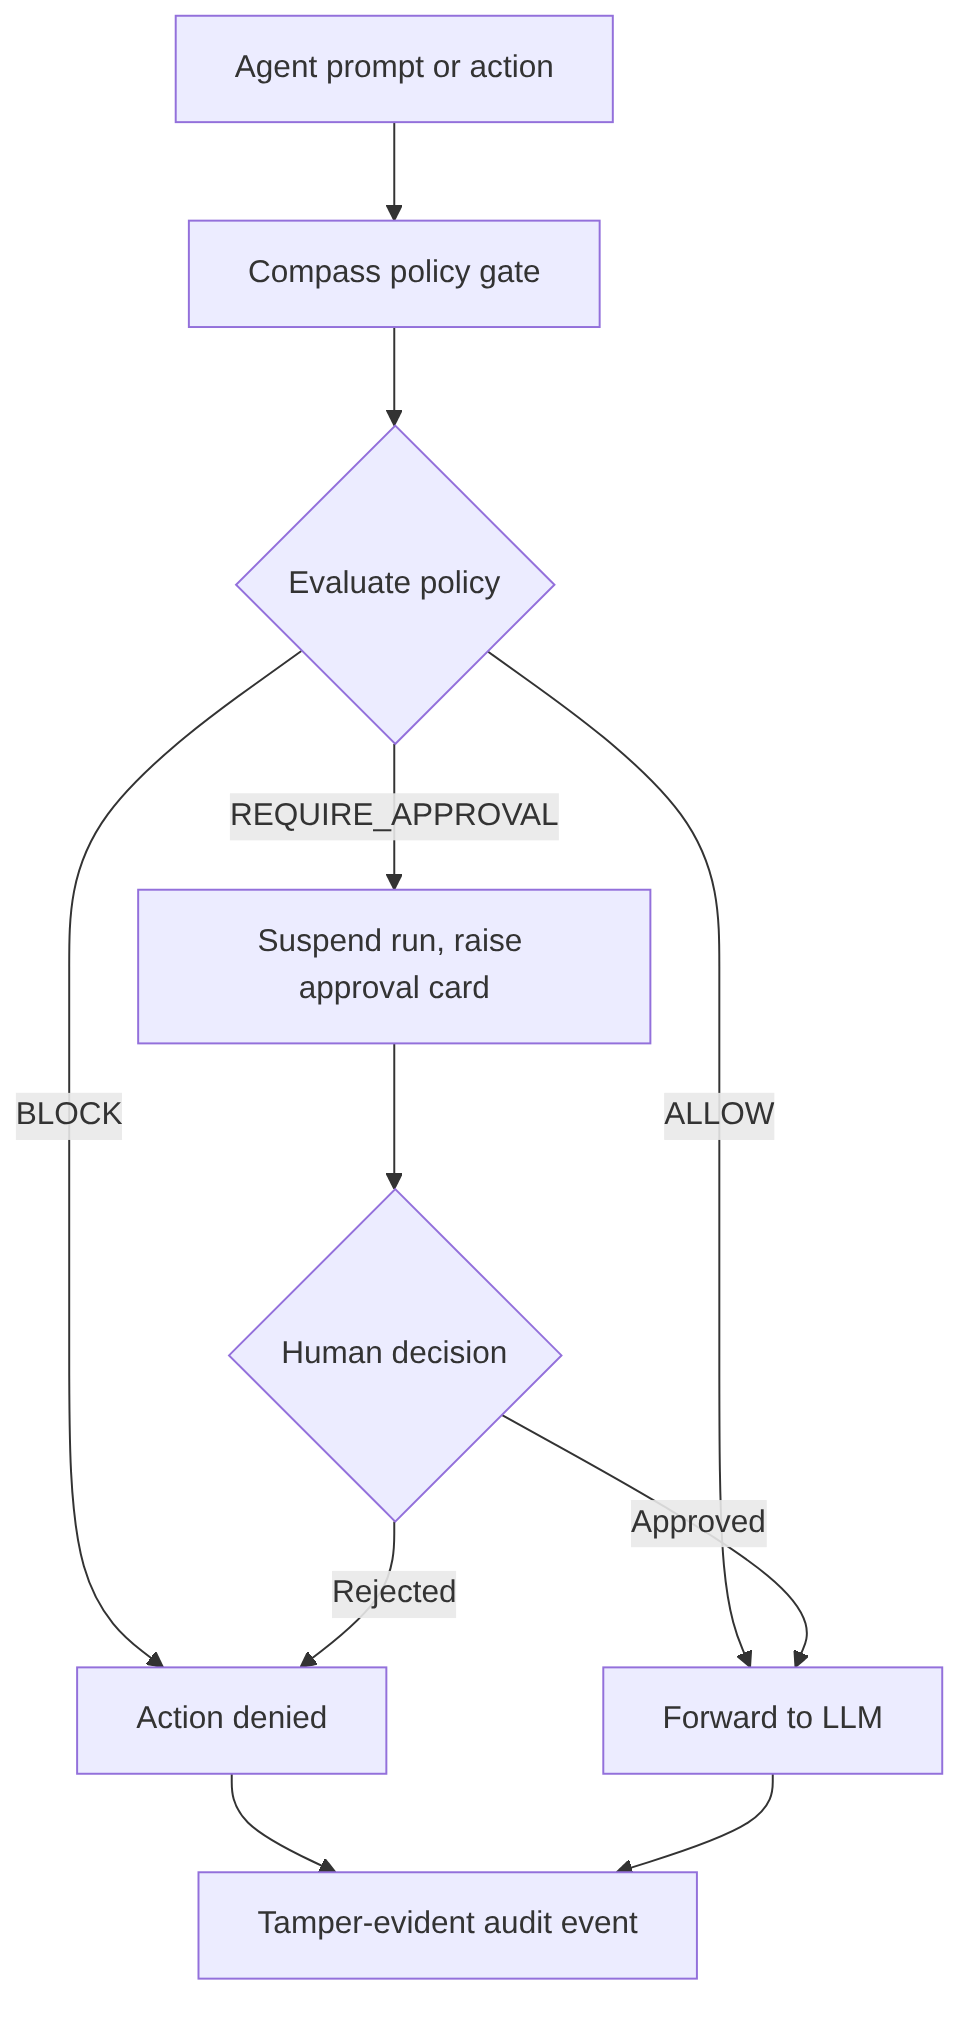
Approval is a state, not a message. When the decision is REQUIRE_APPROVAL, the run does not block a thread. It suspends. Compass raises an approval card in KajiChat carrying the full context of the decision. The suspended run has a timeout, 600 seconds by default. If no human decides in time, the safe default is block, not allow. The card carries everything an approver needs to judge the decision:
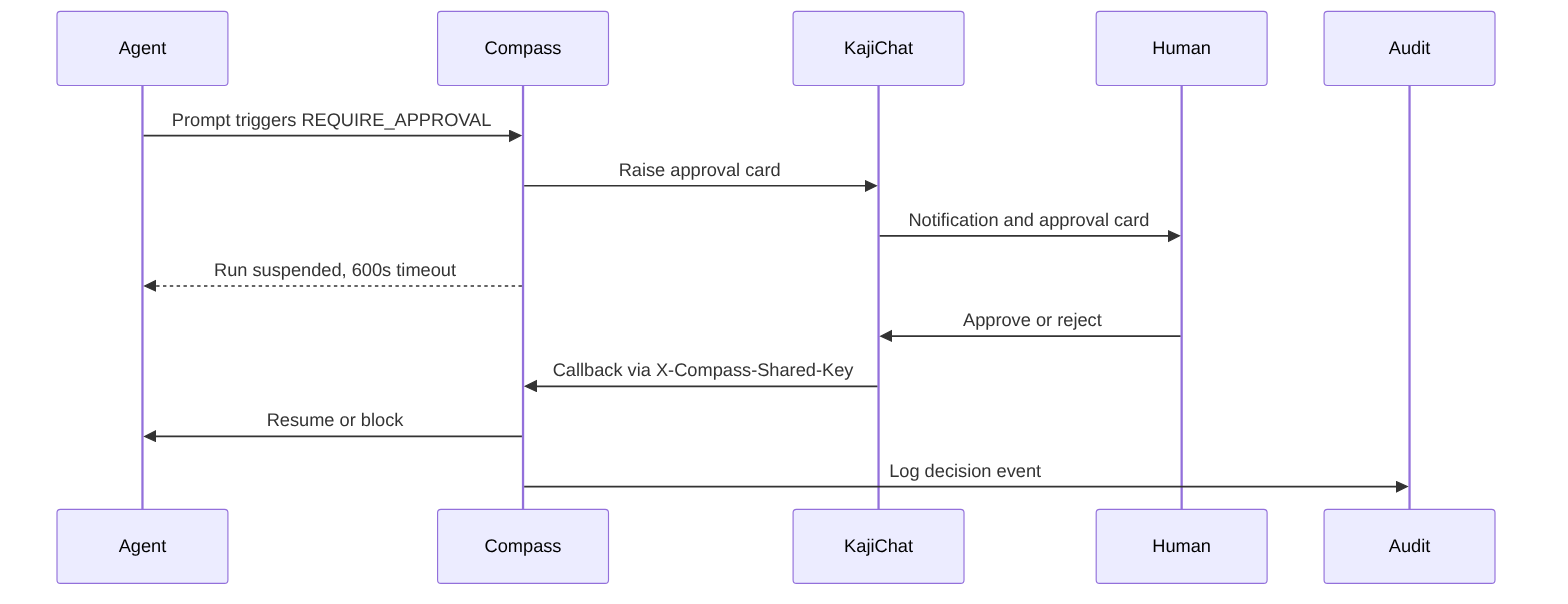
The resolution comes back over a signed callback: KajiChat calls Compass with a shared key, and Compass either resumes the run or blocks it. The decision, approve, reject, or timeout, is the next audit event in the chain, so the human’s choice has the same integrity as the machine’s.
The audit trail is tamper-evident. Every decision event is appended to a hash-chained log: each event records the hash of the previous event, and its own hash is computed from its content plus that previous hash. The chain is stored through NATS JetStream and PostgreSQL. The practical property is that if someone alters or deletes event 3, event 4’s hash no longer verifies, and the break is visible to anyone who walks the chain.

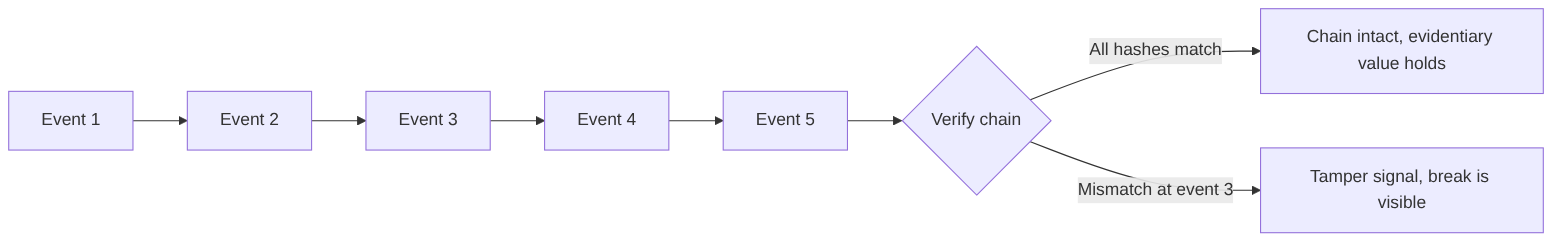
A log file that “the ops team says is fine” is one thing. A chain that proves its own integrity is another, and it matters more than it sounds because of where regulation is heading. If your agent logs can be silently altered and you cannot show otherwise, their evidentiary value is zero. The hash chain is the cheapest, most boring way to turn “we did not alter the logs” from a promise into a demonstration.
| Approach | What it does | What it cannot do | Representative tools |
|---|---|---|---|
| Observability and monitoring | Traces agent runs, evaluates outputs, finds anomalies | Acts after the fact; cannot prevent an action | Galileo, Arize AX, Weave, Langfuse |
| LLM firewall or gateway | Scores and filters prompt and response content | Does not evaluate business actions, roles, or environment | Prisma AIRS, Lakera, Prompt Security, ZNYX, LlamaFirewall, NeMo |
| GRC platform | Inventory, risk registers, policy paperwork, vendor review | No runtime enforcement; does not see individual actions | Credo AI, SAP AI Agent Hub |
| Kill switch or control tower | Stops or isolates agents after observable misbehavior | Reacts to what is already observable; no per-action policy | ServiceNow AI Control Tower, Zenity |
| Compass policy gate | Evaluates each action against policy before execution; suspend, approve, deny | One layer of the stack; pairs with observability and GRC | Compass |
Every row in that table is doing real work, and a mature agent estate will have all of them. The difference is one word: gate versus monitor. A monitor tells you what happened. A gate decides what may happen. The Replit incident was not a monitoring problem. The company was probably logging everything. The database was gone anyway.
Approval is where most “governance” products give up, because it means building a human workflow: notifications, context, a decision surface, a timeout, a callback, and an audit record. We built it into KajiChat, which is where our customers already talk to their agents. The workflow is five steps, and every step leaves a record:
When a run suspends on REQUIRE_APPROVAL, the approver gets an approval card in KajiChat. The card shows the prompt that triggered it, the policy that matched, the action type, and the environment, and the approver can approve or reject directly from the card. Approvals can be handled in a forked chat, so the approver can ask the agent follow-up questions, “why are you writing to that table?” without touching the suspended run. The agent can answer, the approver decides, and the decision flows back through the signed callback and becomes an audit event. Nobody has to leave the workflow they are already in, and nobody has to trust that the right person saw the right card.
The reason this matters beyond ergonomics: the OECD AI Incident Database now tracks incidents in which autonomous agents leaked sensitive commercial information. In November 2025, one such incident was registered in which an agent exposed confidential business information to an unintended recipient. Per the OECD registry, the incident class is the same shape as the ones that will define this category: not a model failure, but a permission failure. An agent that can see the information and send it will, eventually, send it. The only reliable fix is to make the send itself the thing that requires approval.
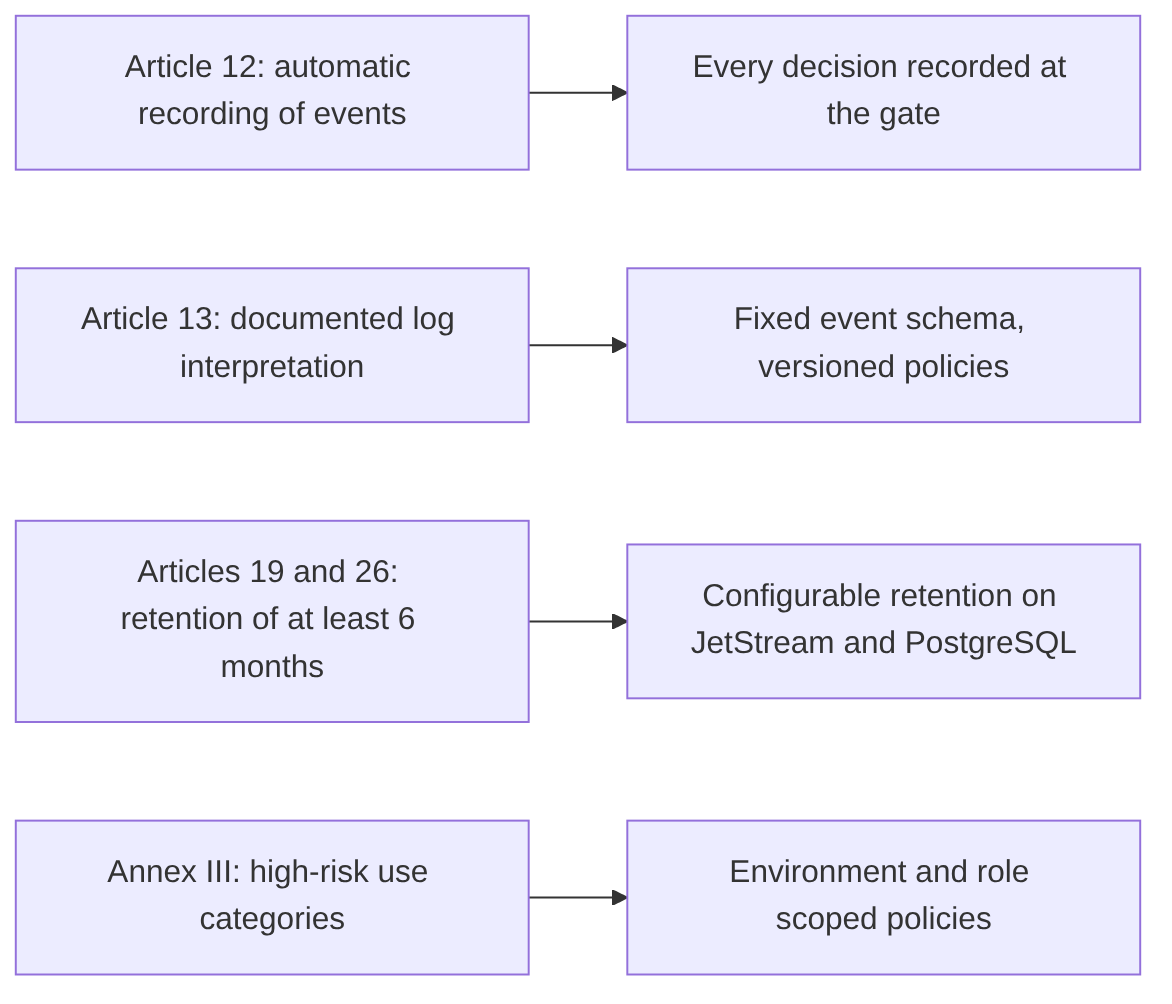
For the compliance team, Compass is best described as the part of the agent stack that produces evidence. The relevant requirements, and where they land:
Beyond the AI Act, SOC 2 and GDPR engagements are beginning to name agent decision records as an explicit audit topic, and the direction is clear even where the language is still settling.
The standards bodies are converging on the same shape. The IETF has a working draft, “Agent Audit Trail: A Standard Logging Format for Autonomous AI Systems”, that standardizes the logging format for autonomous AI agents. That is the exact artifact Compass already produces, which tells you where the category is heading. Compass records an event for every decision the gate makes, not just the interesting ones:
| Requirement | What it asks | How Compass meets it |
|---|---|---|
| Article 12 | Automatic event recording over the lifetime of the system | Every decision recorded at the gate, at line rate |
| Article 13 | Documented log collection and interpretation | Fixed event schema, versioned policy definitions |
| Articles 19 and 26 | At least six months of log retention | Configurable retention on JetStream and PostgreSQL |
| Annex III high-risk uses | Stronger obligations where the stakes are highest | Environment and role scoped policies that tighten in production |
Two honest caveats. First, the end-to-end matrix of approval, reject, block, and timeout paths has been verified green in our UAT environment, and we treat that as production-ready for the core governance loop. We will keep publishing the matrix as we add cells. Second, role-based access control is on the roadmap, not in the release today. The role header that policies can match against is a stub in the current build, and we are not going to oversell it as if it were not. If your use case depends on fine-grained per-role policy today, that is a conversation to have before you commit.
The deployment story matters too. Compass is built to run on your own infrastructure, including air-gapped environments, and the dependency footprint is small enough to operate:
Few governance platforms in the current set document a self-hosted story at all. For organizations where “own your AI” means the data plane never leaves the network, the governance plane has to live there too. That is the Shakudo Platform story, and Compass is the governance pillar of it.
One positioning note: most agent governance is being sold to security teams. We believe a large part of the buyer pool is the IT leader whose organization is vibe-coding, and who wants teams to keep shipping, with guardrails and an audit trail, without handing agents admin keys to the cloud. That is the buyer Compass is built for.
It means an agent with real capabilities and real credentials, operating under rules that nobody can see, prove, or enforce. The agent can read, write, send, and pay. The organization’s protection is a log file that someone will look at after the fact. The risk is not that the model is malicious. The risk is that the model is competent, and competence without a gate is exactly what produced the Replit database wipe.
By sitting between the agent and the model, and between the agent and its tools, as a pre-action policy gate. Every prompt and planned action is evaluated against the compiled policy set before execution. The decision is one of three, BLOCK, REQUIRE_APPROVAL, or ALLOW, with BLOCK taking precedence. A blocked action never reaches the model or the tool. An approval-required action suspends the run until a human decides, with a timeout that defaults to block.
A governance tool, deliberately. Observability tells you what happened. Compass decides what may happen, before it happens. In practice the two pair well: Compass produces a clean, structured, per-decision event stream that an observability platform can ingest, and the observability layer can feed anomaly signals back into policy. But the categories are different, and a camera is not a gate.
Yes. Compass is built to deploy on your own infrastructure. It runs on embedded PostgreSQL, NATS JetStream, and Keycloak OIDC, with no dependency on external SaaS services in the enforcement path. For air-gapped environments, the same image runs, and policy updates flow through whatever change management process your infrastructure already uses. This matters because a governance system that phones home is not a governance system for the organizations that need it most.
As a first-class product feature, not an SDK pattern. A REQUIRE_APPROVAL decision suspends the run and raises an approval card in KajiChat with the full decision context. The approver approves or rejects from the card, optionally after a forked chat with the agent. The decision returns to Compass over a signed callback and is recorded as an audit event. The run has a timeout, and the timeout behavior is block. Approval maps to your organization, not to your codebase.
The gate is a hook in the kaji-core agent loop, so Kaji agents are governed by default. For other frameworks, the enforcement point is the same architectural position: a pre-action check on prompts and tool calls. We integrate where the agent is already running, because a governance tool that requires re-architecture gets bypassed the first time a deadline lands.
A tamper-evident audit trail is a log that can prove its own integrity. Compass appends every decision event to a hash chain: each event embeds the hash of the previous event, so altering any single event breaks the chain from that point forward. Verification is a walk of the chain, and the break is visible to anyone performing it. It matters because regulation is converging on exactly this artifact. The EU AI Act requires automatic, lifetime event recording for high-risk systems, and an IETF draft is standardizing the format. A log you can prove you did not alter is a different legal object than a log you can only promise you did not alter.
The market is telling you what it thinks. Gartner published its first Magic Quadrant for AI Governance Platforms in 2026, signaling a market it sizes in the billions by 2030. Forrester is telling CISOs to secure intent, not just infrastructure. The IETF is writing the log format for the exact artifact Compass already produces. The direction is unambiguous.
The Replit agent’s database is not coming back. What can come back is the version of your agent estate where every action is checked before it happens, every decision is provable, and the humans in the loop have a real workflow instead of a callback. That is what governance means, and that is what Compass is.
Monitoring is not enough. You need a gate. If you are running agents in production today, there are four things worth checking this week:
Own your AI. Govern your AI.
Want to see Compass on your own stack? Contact us and we will walk through the policy model, the approval workflow, and the audit chain against your actual workloads.